
Cursor’s own models: Auto as the floor, Composer / Grok, and when to pay for Opus 4.6
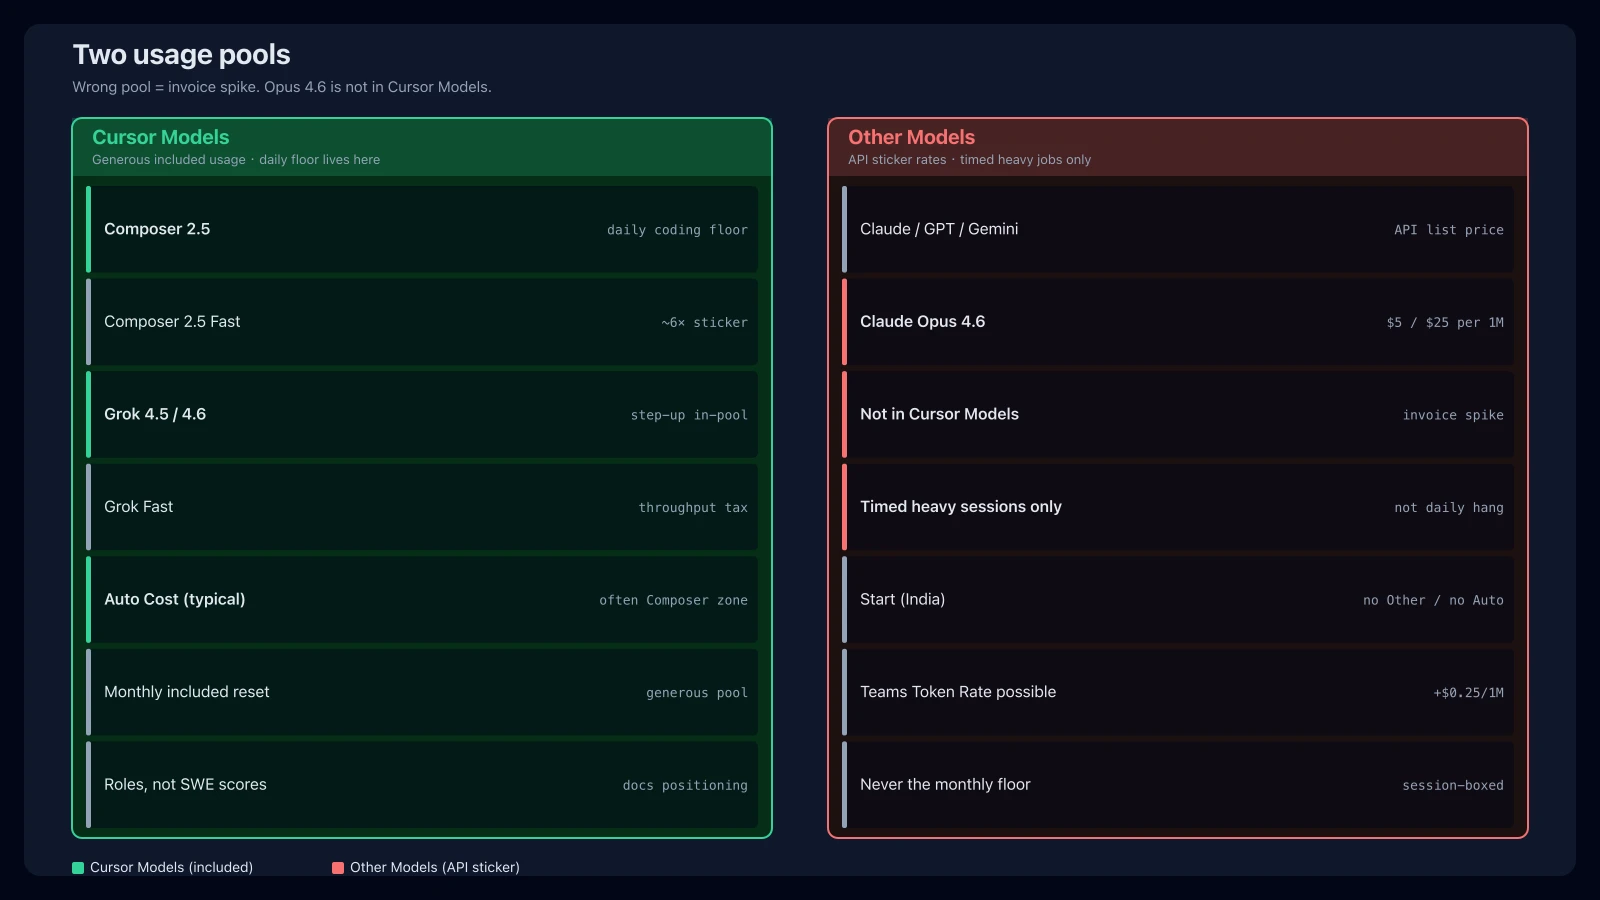
Two usage pools: Cursor Models (Composer / Grok) is generous; Opus 4.6 burns Other Models. Auto is a router, not a fourth model — Auto Cost = daily floor. Same 100K+20K job: Composer ~$0.10, Grok ~$0.32, Opus ~$1.00. Not an independent benchmark.
 Enlarge image
Two pools first (the beginner trap)
Your bill is not one big pool. Officially there are two, resetting with the billing cycle:
- Cursor Models: first-party
Composer 2.5,Grok 4.5,Grok 4.6(plus Fast variants) — usually the generous pool - Other Models: Claude / GPT / Gemini at each model’s API sticker; Opus 4.6 lives here (~$5/$25 per 1M)
One line: pick the wrong pool and the invoice explodes — that is not “unused subscription.” Start (India) has no Other Models pool and no Auto.
Auto: say it as the floor, not a fourth model
Product facts — no myths:
- Auto is not a standalone model named Auto. It is Cursor Router.
- Three modes:
Cost/Balance/Intelligence. - After 2026-08: you pay the list price of the model each request is routed to — not one flat “Auto is cheap” sticker.
- Start does not include Auto. On Teams, routing to a third party can add the Cursor Token Rate (+$0.25/1M); Grok / Composer are exempt.
Beginner lines you can reuse:
- Auto Cost = daily floor: hang it when you refuse to pick models and only need “good enough, don’t torch quota” — a floor tier, not the strongest tier.
- Floor ≠ free / ≠ always cheapest: Intelligence can route to expensive models.
- Floor ≠ beating Opus: for hard work, hand-pin Grok or Opus.
- For predictable cheap coding, pin Composer 2.5 — steadier than gambling on the router.
| Option | Good for | Bad for |
|---|---|---|
| Auto Cost (floor) | Daily hang / no picker / small edits | “Strongest”; fixed unit price; hard architecture |
| Auto Balance | Lazy mid tier | Bill control + Opus-class hope |
| Auto Intelligence | Occasional lift, still lazy | All-month default (quota killer) |
| Composer 2.5 | Predictable cheap coding floor | Huge multi-repo hard reasoning |
| Grok 4.5 / 4.6 | Step up inside Cursor Models | Free Opus substitute |
| Opus 4.6 | Timed heavy jobs | All-day floor |
First-party models: how to read coding ability
 Enlarge image
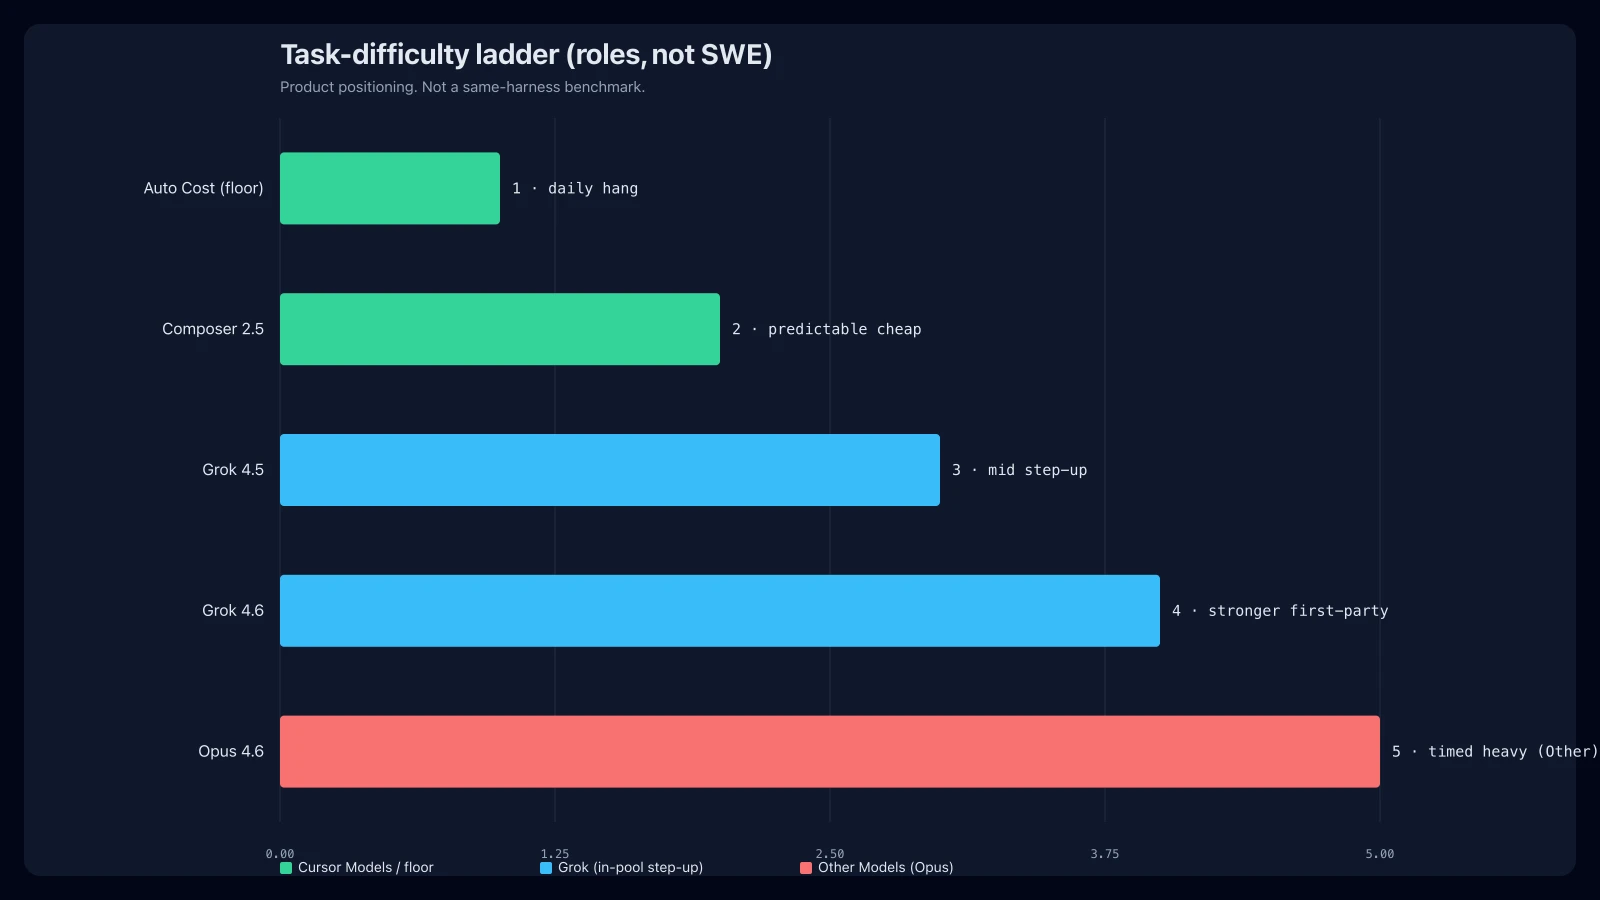
This is role division (product positioning / docs — not an independent harness):
| Model | Good for | Bad for |
|---|---|---|
| Composer 2.5 | Edits, complete, small refactors, daily Agent | Long multi-repo architecture |
| Grok 4.5 | Stronger daily, mid value | Hard-top Opus claim |
| Grok 4.6 | Stronger Cursor Models tier | Still ≠ free Opus |
| Composer / Grok Fast | Throughput you will pay for | Default when saving quota |
Versus Opus 4.6: the step up for multi-file agents, nasty bugs, design trade-offs, hard long-context work. Weights are not downloadable; sticker and usage pool differ. Do not write that Grok “already beat Opus.”
Price: first-party gaps, and the Opus gap
 Enlarge image
Official Cursor Models stickers ($/1M):
| Model | In $/1M | Out $/1M | vs Composer |
|---|---|---|---|
| Composer 2.5 | Best in this comparison $0.50 | Best in this comparison $2.50 | 1× |
| Composer 2.5 Fast | $3.00 | $15.00 | ~6× |
| Grok 4.5 / 4.6 | $2.00 | $6.00 | ~4× in / ~2.4× out |
| Grok Fast | $4.00 | $12–18 | Higher |
| Opus 4.6 | $5.00 | $25.00 | ~10× in / ~10× out |
Do not invent an “Auto unit price” column — Auto is not its own $X/$Y SKU. Cost tends toward cheaper routes; it does not guarantee them.
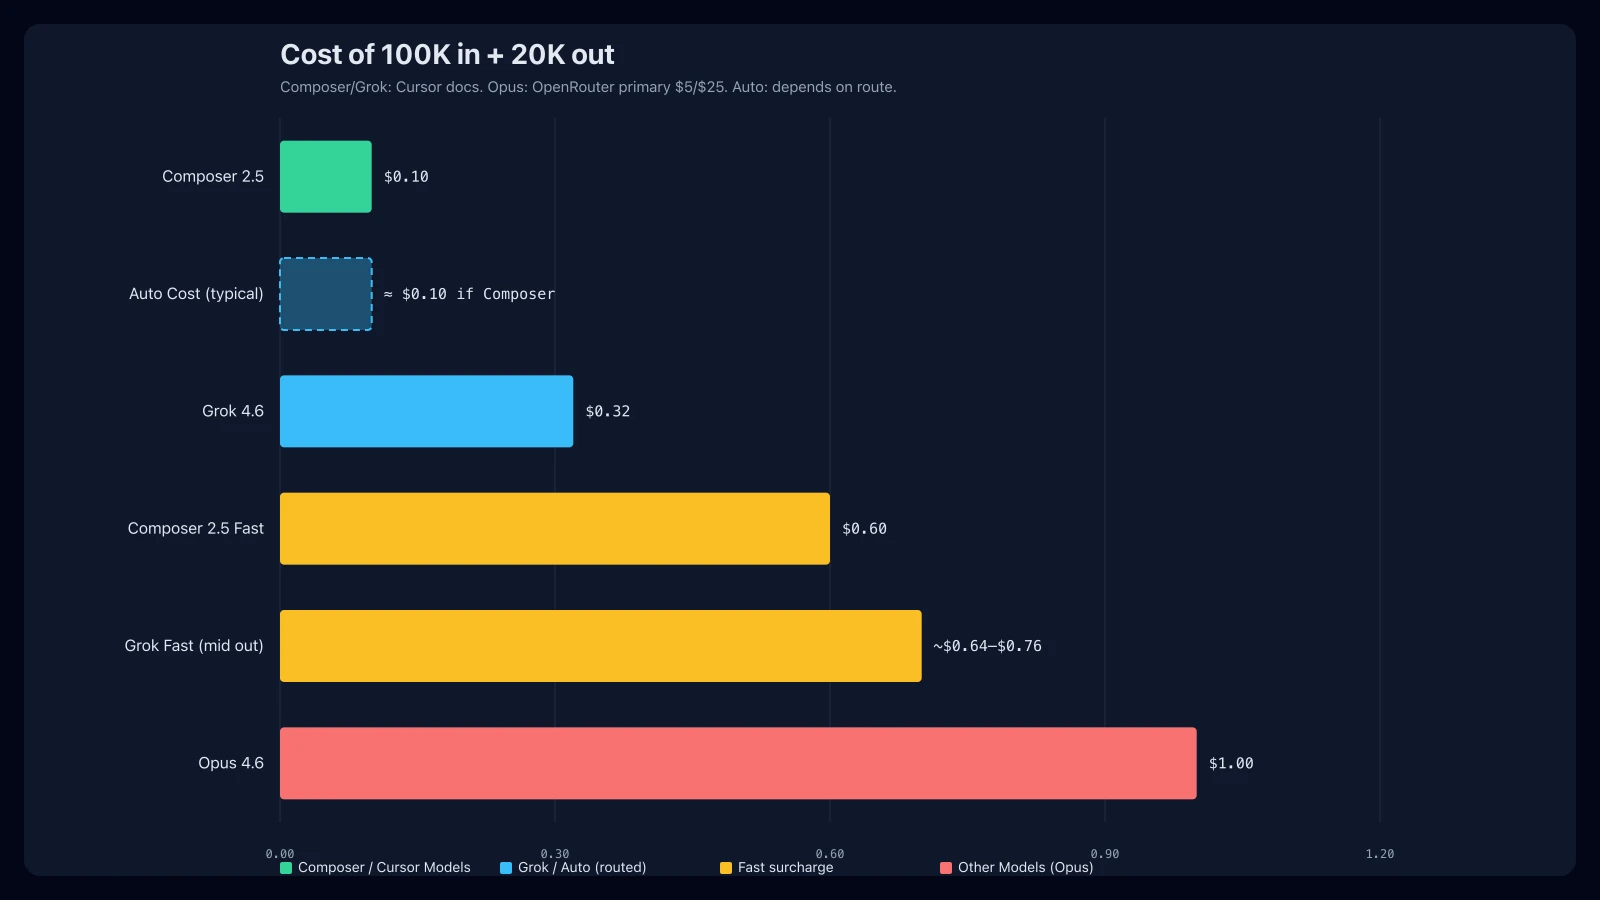
Hold the job fixed at 100K in + 20K out (same ruler as other on-site insights):
| Model | Job $ | Note |
|---|---|---|
| Composer 2.5 | ~$0.10 | Cursor Models floor |
| Grok 4.6 | ~$0.32 | Same pool, stepped up |
| Opus 4.6 | ~$1.00 | Other Models pool |
| Auto | routed model’s row | Floor hopes Composer zone; not guaranteed |
Real invoices also move with included pools, cache, Fast, and Teams Token Rate. This table is only who you pay for the same token work.
How to pair them without burning quota
 Enlarge image
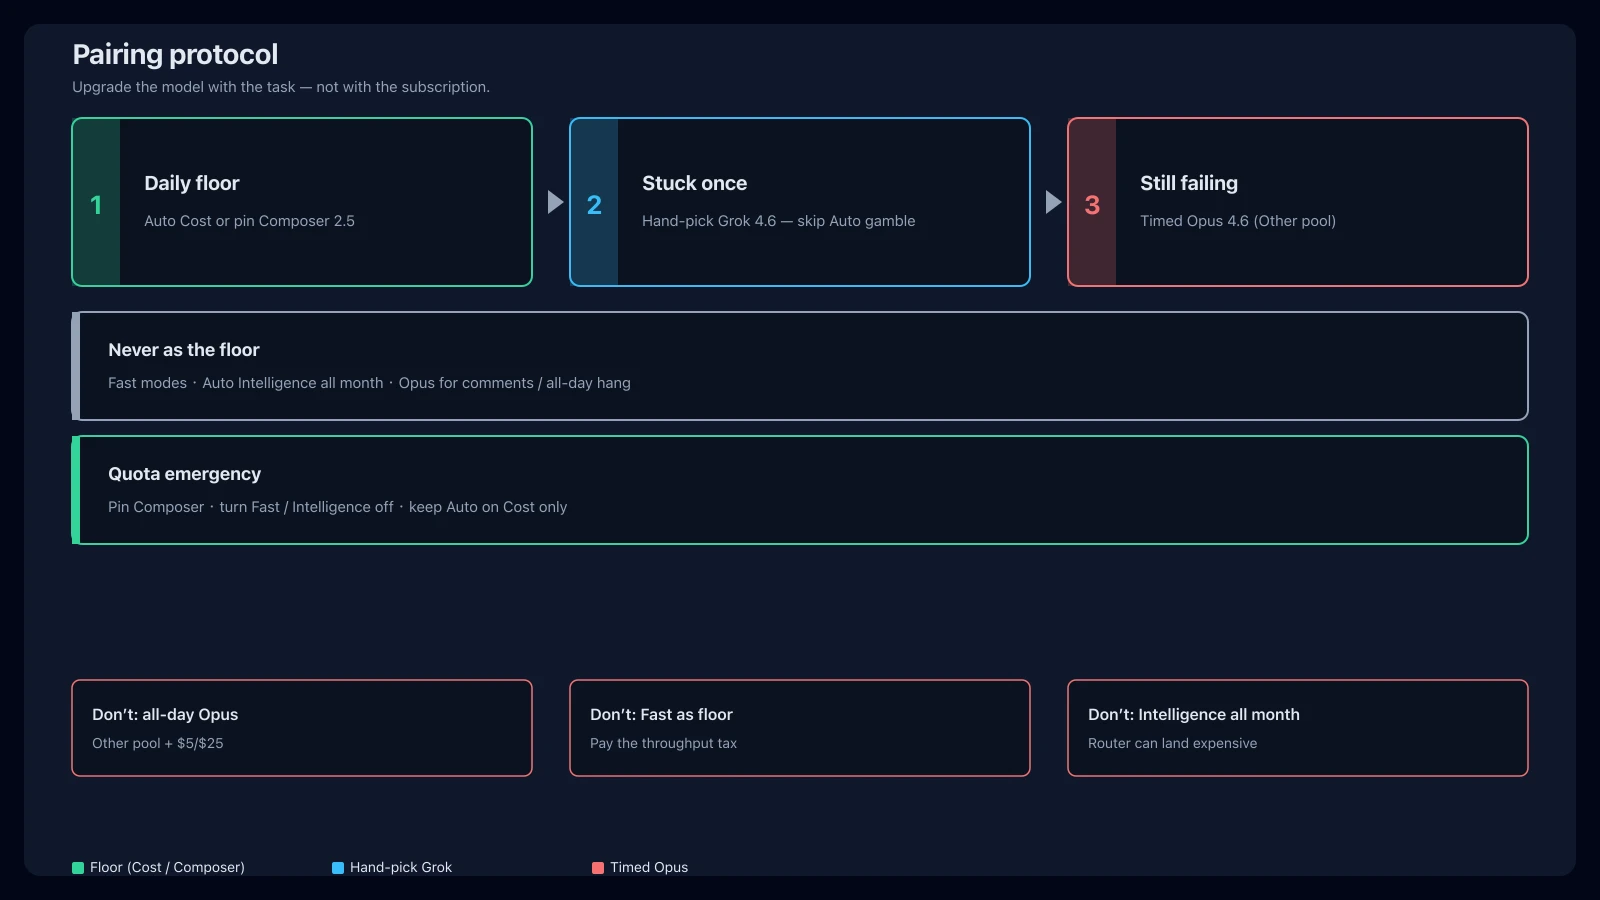
Copy-paste protocol:
- Daily floor: hang Auto Cost, or pin Composer 2.5 for a predictable bill.
- Stuck once: stop gambling on Auto — hand-pick Grok 4.6, do not jump to Opus.
- Still failing / architecture-grade: Opus 4.6 for one long session / one design / one failing test set.
- Fast / Auto Intelligence: only when latency or difficulty is explicit — never the floor.
- Don’t: all-day Opus; Opus for comments; Auto as “infinitely cheap magic.”
| Scene | Pick | Fallback |
|---|---|---|
| Daily hang / lazy picker | Auto Cost (floor) | Pin Composer |
| Tab / tiny edit | Composer or Auto Cost | — |
| Single-file bug | Composer → hand-pick Grok | Opus (hard repro only) |
| Multi-file Agent | Hand-pick Grok 4.6 | Opus |
| PR review / security-sensitive | Opus or Sonnet-class | — |
| Quota emergency | Pin Composer; off Fast / Intelligence | Auto Cost only |
Three lines to nail about Opus 4.6
- Stronger ≠ all-day use; the cost is the Other Models pool + sticker.
- Cheap Auto / Composer ≠ useless; most sessions should stay on the floor or Cursor Models pool.
- “Scientific” = upgrade the model with the task, not the subscription; floor owns the day, Opus owns the spikes.
Don’t: treat Auto as a fourth fixed-cheap model; run Intelligence as the monthly floor; force Opus on Start; default Fast; invent “Grok already beat Opus.”